InvarLock 0.16.0: Native, Captured and Judge Evidence
Compare saved evaluator answers through the main commands, collect judge ratings under a declared rubric, and read the result beside the checks that explain it.

If your evaluation pipeline already saves both models' answers for each case, InvarLock 0.16 can compare those records through its main commands. You can keep the evaluator you use and give another reviewer the records needed to check its result.
The release brings captured results and judge measurements into the existing evaluate → verify → report workflow. Native comparisons bind model files and runtimes; captured comparisons use saved evaluation records; judge measurements assess fixed answers against a declared rubric. Each path retains the facts its scoring method needs.
At a glance — v0.16 release snapshot
- Supported evaluator exports can supply paired records through the main commands.
- Exact match, measured likelihood and bounded judging each require their own per-case facts.
- Hosted-service checks distinguish fresh observations from replay of older evidence.
- Redesigned offline reports put the policy result beside the checks that explain it.
- Core, first-party add-ins and example files use matching release versions.
Start with the records you already have
Suppose an evaluation pipeline already retains the baseline and changed model's answer for each case. The captured-results workflow can compare those records without asking the pipeline to move to another evaluator. One request identifies both complete runs, the comparison policy and where to write the evidence.
An export containing only accuracy: 0.71 is not enough. A verifier needs the individual cases to reconstruct the scores and comparison. The required facts depend on the scorer:
| Scoring question | Records needed |
|---|---|
| Exact match: did the answer match the reference? | Both sides' answers and reference strings for the same cases |
| Normalized negative log-likelihood (NLL): how likely was the reference text? | Measured log probabilities, byte and token counts, and exact input and model identities |
| Bounded judging: how did fixed answers rate under the rubric? | Task inputs, both sides' fixed answers, the rubric, collection plan and saved judge calls |
Likelihood needs actual measurements. InvarLock cannot reconstruct it from generated answer text, token usage alone or a summary score. Captured replay checks the supplied records; it does not prove that the original model execution happened as claimed.
Judge fixed answers under a declared rubric
Judging starts with fixed baseline and candidate answers. The collection plan declares the rubric, judge configuration, sampling choices and call limits before ratings are collected. Keeping the answers fixed lets another reviewer replay the recorded analysis without generating different answers or making new provider calls.
The optional invarlock-inspect-judge package collects the ratings. Core handles offline import, analysis, verification and reporting. Repeated ratings do not create more independent test cases, and successful replay does not establish that the ratings are correct or that the judge is generally accurate. The judge reference describes those statistical and verification boundaries.
Choose examples carefully. Comparing already-recorded scalar ratings is not the same as collecting bounded judge measurements. An evidence set can require both deterministic scoring and a judge comparison over the same answers, but their uncertainty statements remain separate. Combining the reports does not create one joint confidence guarantee.
Recheck a hosted service with fresh observations
A hosted service may expose an endpoint name and revision without giving the caller access to immutable model weights. Captured evidence can record that service configuration, the evaluation harness and the observation window. The service's stated revision remains a claim from the source, rather than independent proof of which weights ran.
For a periodic check or an incident review, collect fresh observations, then compare and verify them. Replaying yesterday's pack checks yesterday's evidence. It does not measure the service again or establish continuous monitoring. The hosted-service guide follows the process from baseline approval through fresh capture and review.
Read the policy result beside the checks that explain it
The redesigned offline report leads with the policy result and its supporting checks. It shows the baseline and candidate identities, recorded differences, metric values, uncertainty and numerical requirements together. Reports with several metrics or evaluation scopes include an overview and navigation. Failed checks remain visible.
Read a policy pass beside its requirements
- Observed change: +0.5 pp
- Ministral 3 8B exact-match accuracy: 44.75% → 45.25%, over 400 pairs.
- Paired 95% interval: −1.12 to +2.119 pp
- Its lower bound clears the −2 pp requirement. It includes zero, so this does not demonstrate improvement.
- Other requirements also pass
- At least 400 records, interval width at most 10 pp, and at least 20% accuracy on both sides.
An actual v0.16.0 report excerpt from retained evidence, not a new run. Rendering the report does not supply independent trust inputs or deployment approval.
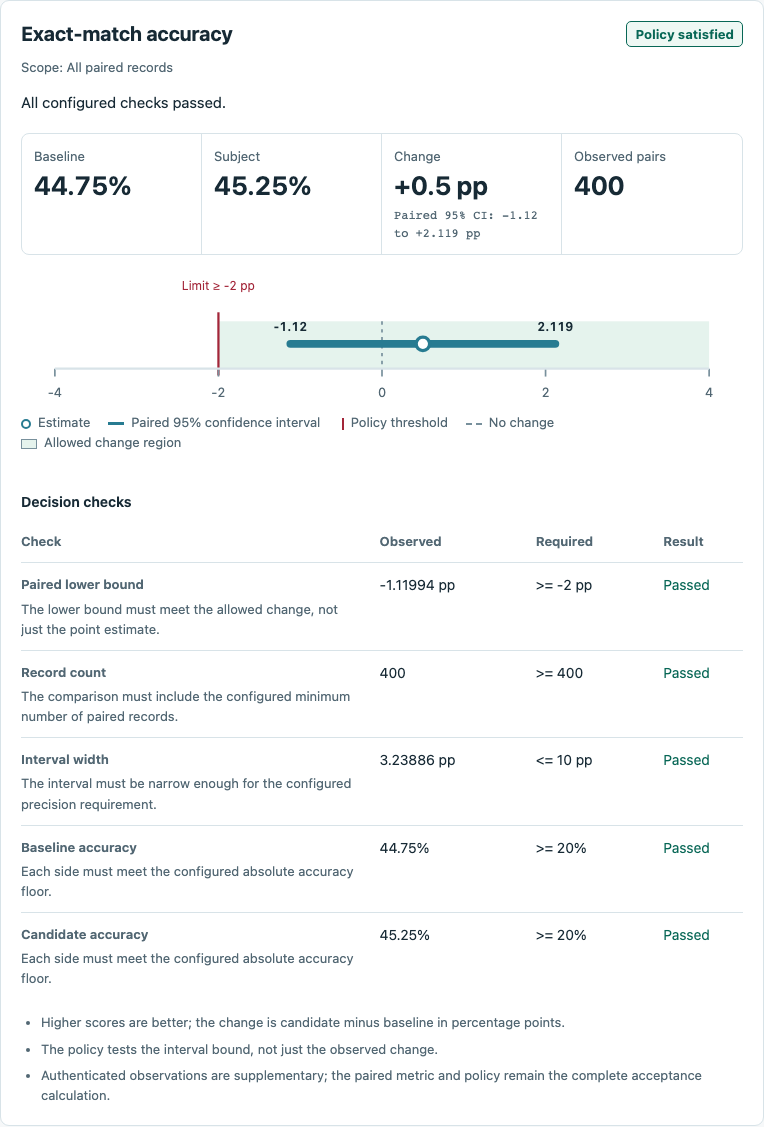
Read the interval beside the rule: the lower bound clears this comparison's −2 percentage-point requirement, even though the interval includes zero. The record count, interval width and both accuracy floors also have to pass. The higher point estimate alone would not settle the result.
HTML reports support mobile layouts, dark mode and printing every metric. Console, Markdown and JUnit outputs serve other review and automation workflows; the report reference covers each format.
Try the release and update existing workflows
Install the lightweight core with Python 3.12 or newer:
python -m pip install "invarlock==0.16.0"
The tagged five-minute quickstart verifies retained evidence on a regular CPU, issues a fresh signed receipt and renders HTML. It does not run a model. To create a first captured comparison, use the synthetic extraction starter in the captured-results guide. Its invented cases demonstrate how the workflow fits together; they say nothing about a real model's quality.
Keep core, first-party add-ins and example files on the same release. For model execution, follow runtime setup: maintained runtime images and source-checkout dependency groups replace the retired public inference extras, including hf.
Captured workflows now use v2 requests through the main commands and the invarlock.engine Python interface. If migrating affected legacy captured evidence, recreate it from reviewed source records. The recipient must independently approve the new expected digests and signer identities—the values used to check that the supplied evidence is the intended comparison.
Native v1 evidence, native v1/v2 receipts and the v0.13 compatibility promise remain unchanged. Historical evidence retains its original bytes and meaning.
What this release still leaves to review
Choose the workflow from the records you have and the question you need to answer. Saved answer strings can support exact match, but cannot supply missing likelihood measurements or judge ratings. The bounded judge example demonstrates its own path; it does not extend the separate native model qualifications. The receiving team still decides whether the workload, requirements and result support its proposed use.
Sources
Website documentation explains the maintained workflow. The changes described here belong to InvarLock v0.16.0; the tagged release record preserves that scope. Retained comparisons keep their original evidence identities and qualification limits.
- Captured results
- Judge measurements
- Evidence sets
- Hosted-service requalification
- Reports and receipts
- Runtime setup
- Compatibility covenant
- Release verification
- InvarLock v0.16.0 release record
- Tagged v0.16.0 changelog
- Five-minute signed-evidence check
- Tagged v0.16.0 Ministral 3 8B report used in the excerpt
More in Release
Explore nearby related posts.
Release note
InvarLock 0.17.0: Plan the Comparison, Explain the Result
Check judge-evaluation precision before collection, explore exact-match sensitivity, and rehearse reassessment while preserving earlier evidence.
Release note
InvarLock 0.15.0: Replayable Deployment Evidence and Bounded Decisions
InvarLock 0.15 adds replayable deployment evidence, an absolute accuracy floor, four retained evaluator journeys, and a protected consumer example.
Release note
InvarLock 0.14.0: Evaluator Evidence In, Recipient Policy Out
v0.14 normalizes external evaluator records, then hands a signed technical receipt to recipient-owned trust and acceptance rules.