Check the answers behind three passes
Reproduce the original statistics and the new answer-change analysis from saved public records. Each comparison contains 400 pairs. Across the three deployments, the 1,200 rows cover the same 400 question IDs.
Download the reproduction package
The ZIP contains a small CSV, three unchanged reports, source locations and hashes, Python code, option labels, runtime settings and four charts. No model weights, private material or benchmark prompts are included.
1. Reproduce the results offline
Unzip the package, open its gguf-answer-review directory and use Python 3.12 or later. No additional packages are required.
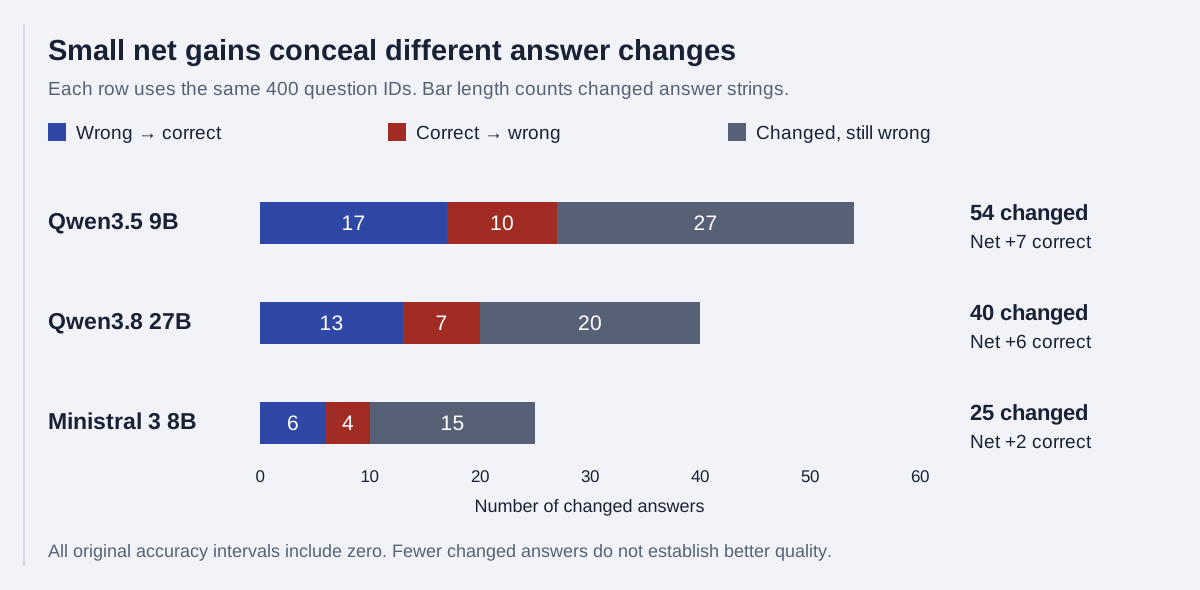
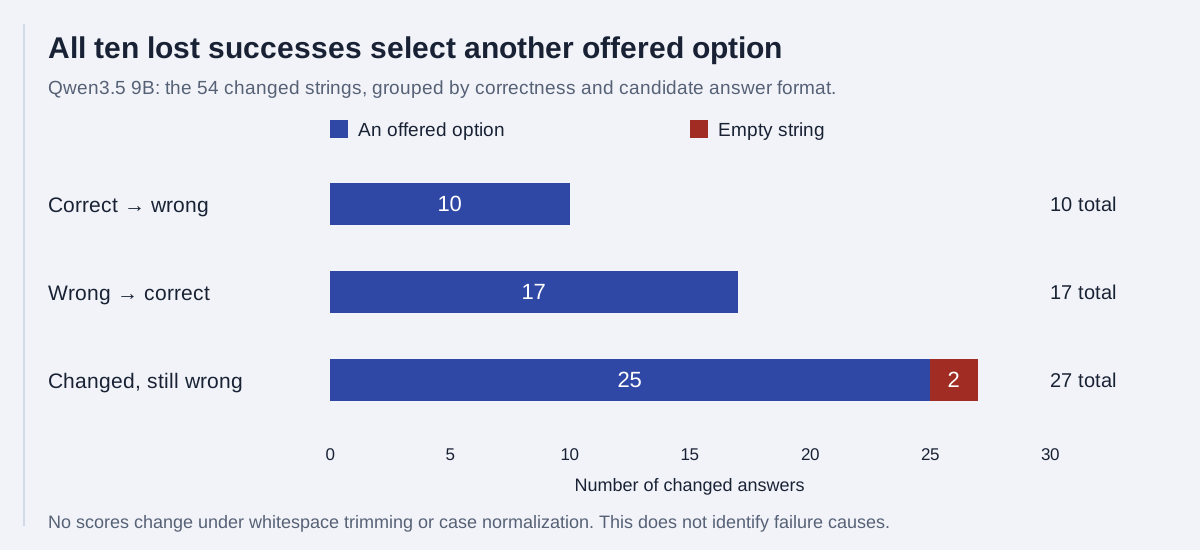
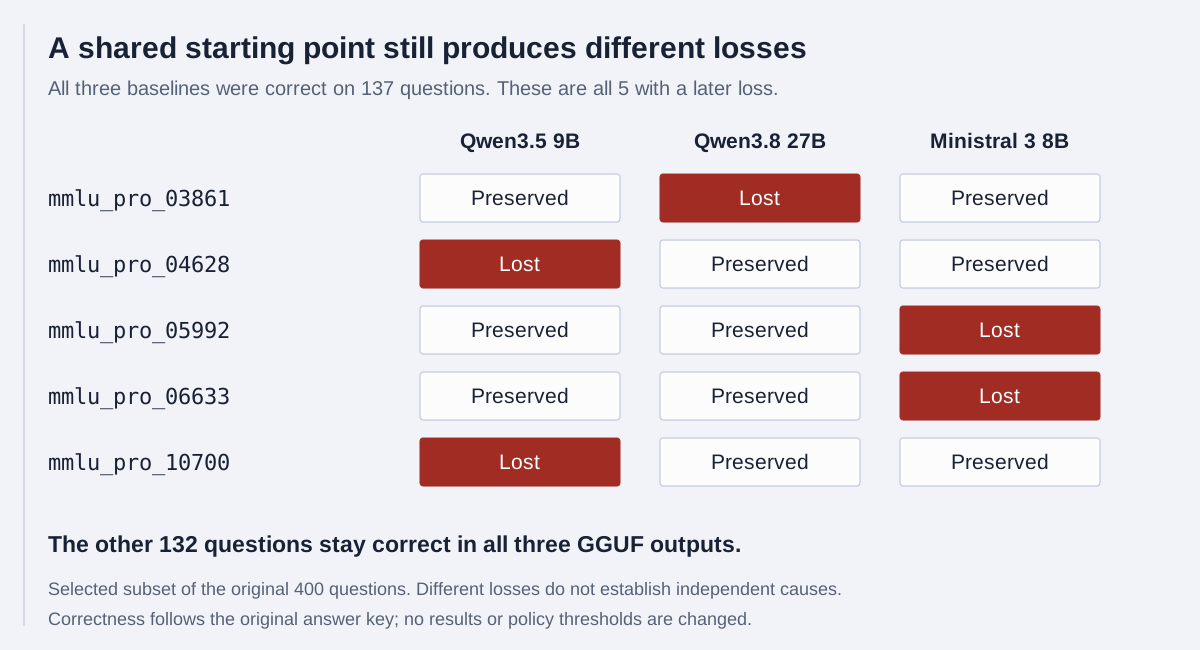
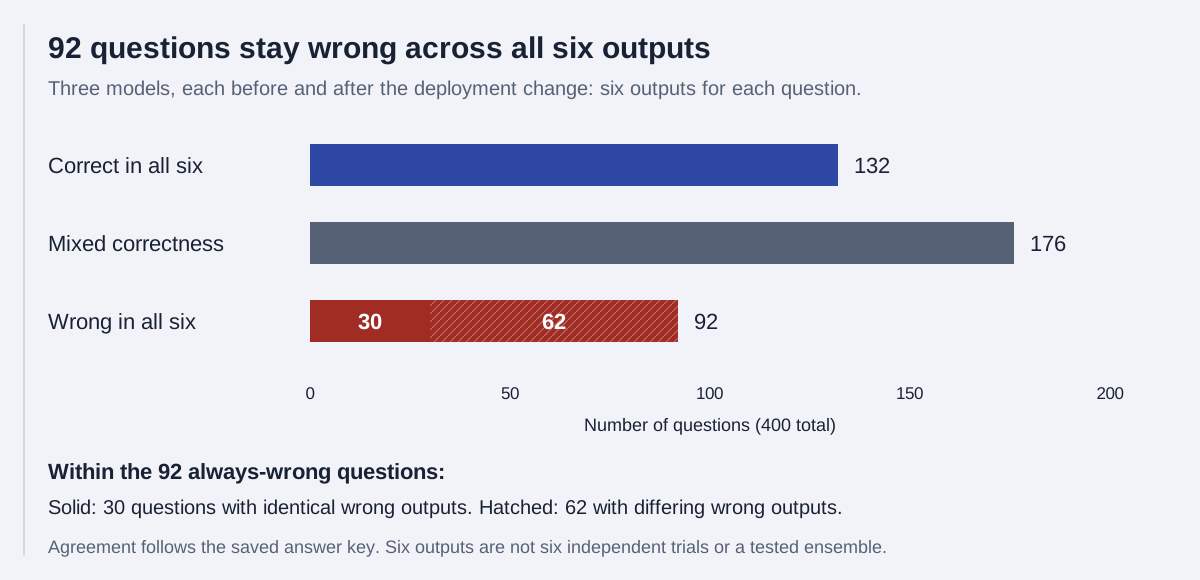
python3 reproduce.py --output reproducedThis checks file identities, every row and the literal exact-match scores. It recalculates original counts, accuracies, paired Newcombe v2 95% intervals, exact two-sided McNemar statistics and policy passes. It also reproduces gains, losses, changed-but-wrong answers, empty outputs overlap between loss lists, option validity, normalization sensitivity, shared baseline successes, persistent errors and opposite-direction cases.
The new reproduced directory contains the original summary.json, the new review-summary.json and all four SVG charts. It must not already exist. The statistics module is copied unchanged from the original release; this reproduces that method rather than independently validating it.
2. Check the extraction against the originals
This optional command downloads 27 immutable public JSON files from the original v0.15.0 source commit and checks their hashes. It then reconstructs the CSV from the schedules, observations and paired records, requiring complete ordered matches. It also checks the offered-option projection against all three prompt schedules, and the six runtime receipts against their manifests.
python3 reproduce.py --fetch-sourcesDownloaded JSON is read as data; no downloaded code is executed. With a local checkout of the pinned source revision, use --source-root /path/to/invarlock instead. The source manifest names every file and hash.
Inspect the supporting files
- All 1,200 projected answer records — includes unchanged and unfavorable outcomes. Empty answer fields preserve recorded empty strings; they are not missing observations.
- Offered options and question digests, runtime context, and complete follow-up findings and question lists.
- Computed summary and complete loss lists — 21 distinct lost question IDs, with no overlap between deployments.
- Analysis and chart code with follow-up analysis and chart generators, and original statistics implementation.
- Unchanged original reports: Qwen3.5 9B, Qwen3.8 27B, Ministral 3 8B.
- Charts: answer changes, answer validity, shared starting point, persistent shared errors. See also full instructions and worked-example notes, package hashes and statistics-code license.
What these checks establish
The original results, thresholds and verdicts are unchanged. These are retrospective descriptive checks, with no new inference, conversion or experiments. They do not verify signatures or establish genuine original execution, failure causes, error severity, broader performance or deployment suitability. The six related outputs per question are not independent trials; shared failures follow the original answer key. The one-token budget does not explain empty outputs.
For signature verification and independent trust inputs, follow the public evidence guide. The analyses here use source commit 4f036ffe99cfaa82019c90ea527b8c4291a091b3. All original accuracy intervals include zero.